How AI Phone Agents Handle Background Noise and Poor Call Audio

How AI phone agents handle background noise across codecs, VAD, ASR, and telephony, with practical guidance on denoising, interruptions, and graceful recovery.
Background noise problems in AI phone agents rarely start and end with a loud caller environment. Speech passes through a microphone, handset processing, mobile or fixed networks, PSTN or VoIP infrastructure, codecs, streaming services, speech recognition, and turn-taking logic. Every stage can strip information, inject interference, or delay the conversation.
What follows traces that path in order. It is written for developers, AI engineers, product teams, and contact center leaders who need to distinguish audio enhancement from model robustness, tune real-time behavior, recover from uncertainty, and test with calls that resemble production rather than studio recordings.
Contents
Where call audio degrades: Trace faults from the caller's surroundings through telephony transport.
Audio cleanup versus robust recognition: Understand why denoising and noise-robust ASR solve different problems.
Real-time speech and turn handling: Tune streaming, voice activity detection, thresholds, and barge-in.
Recovery under uncertainty: Use confidence, context, reprompts, and human escalation safely.
Production testing: Build realistic scenarios and measure recognition, latency, triggers, and task outcomes.
FAQ and takeaways: Resolve common implementation questions and prepare for deployment.
Where does poor call audio enter the system?
Start with the source. A customer on a busy street produces traffic, wind, and nearby voices. Inside a moving vehicle, road vibration, cabin reflections, and hands-free echo compete with speech. Cafes and open offices are particularly difficult because background conversations carry speech-like structure, so both ASR and VAD can mistake them for the caller.
Common failure sources and their engineering effects
Source | What reaches the agent | Typical response |
|---|---|---|
Environment and microphone | Wind, music, competing talkers, low volume, clipping | Moderate suppression, gain checks, robust ASR, clarification |
Acoustic echo | The agent's synthesized voice returns through speakerphone | Echo cancellation, playback-aware VAD, barge-in tuning |
Mobile network | Dropouts, time-varying distortion, weak uplink | Jitter buffering, packet-loss handling, conservative recovery |
PSTN or VoIP transport | Narrow bandwidth, transcoding, jitter, packet loss | Codec-aware models, streaming buffers, transport monitoring |
Conversation behavior | Overlapping speech, interruptions, long pauses | Turn detection, interruption policy, explicit reprompts |
Telephony systems often limit audio bandwidth and may introduce compression or transcoding artifacts. Narrowband telephony preserves a smaller speech-frequency range than modern wideband recordings, and repeated transcoding can add further degradation. Once signal detail is lost during encoding or transmission, downstream processing cannot reconstruct the original signal exactly. See the primer on audio codecs for the transport fundamentals.
What teams often get wrong: They treat a weak mobile connection as stationary background noise. Packet loss and codec corruption create missing or malformed speech, so a denoiser has little valid signal to recover.
Should you clean the audio or make recognition more robust?
Improving incoming audio means transforming the waveform before recognition. Noise suppression estimates and attenuates traffic, fans, music, or stationary hum. Echo cancellation removes a correlated copy of agent playback. Automatic gain control can raise low-volume speech, though aggressive gain amplifies noise along with it. These components belong to AI call audio processing, not to ASR itself.
Making ASR robust means training or adapting voice agent speech recognition to decode speech despite codec artifacts, reverberation, variable signal-to-noise ratio (SNR), accents, and realistic noise. Noise type matters as well as SNR: different interference patterns can affect recognition differently, so speech recognition performance in background noise should not be summarized by a single SNR figure. Smallest.ai discusses related challenges of AI speech recognition.
Stronger filtering is not automatically better. Excessive denoising can erase unvoiced consonants, soften word boundaries, create musical artifacts, or suppress quiet speakers. Evaluate intelligibility and downstream transcription accuracy, not just whether the waveform sounds cleaner.
Production systems usually combine restrained enhancement with noise-robust ASR. Smallest.ai's speech stack includes Pulse for speech-to-text and Atoms for building voice agents, letting teams evaluate recognition alongside conversational behavior rather than treating noisy phone call transcription as an isolated benchmark. That said, platform choice does not remove the need to validate codecs, routing, and caller conditions in your own deployment.
How do streaming systems detect speech, turns, and interruptions?
Streaming audio processing works on short frames rather than waiting for a complete recording. The system continuously updates speech probabilities, partial transcripts, endpoint estimates, and dialogue state. Shorter buffers reduce responsiveness delays but expose the pipeline to more unstable evidence; larger buffers smooth decisions at the cost of making the agent feel sluggish.
Tune VAD thresholds for the actual channel
Voice Activity Detection (VAD) decides whether frames contain speech. A low detection threshold catches quiet callers but also fires on cafe conversations, car turn signals, keyboard noise, or hold music. A high threshold cuts false triggers but clips low-volume words and delayed syllables.
Use separate start and stop criteria, minimum speech duration, hangover time, and playback-aware logic. A single threshold is rarely sufficient for AI voice agent background noise. VAD is a gate, not proof of meaning: false positives can push background noise into ASR, while false negatives can clip real speech.
Treat barge-in as a verified event
When a caller interrupts the agent, rapid barge-in should stop synthesis and route speech to ASR. Triggering on any sound causes the agent to halt for echo or a slammed door; requiring a complete transcript before reacting feels unresponsive. A practical policy combines VAD persistence, echo-cancelled energy, partial ASR evidence, and conversational context. When two people speak simultaneously, preserve the audio and acknowledge the collision rather than fabricating one clean turn.
How should the agent recover when it cannot understand?
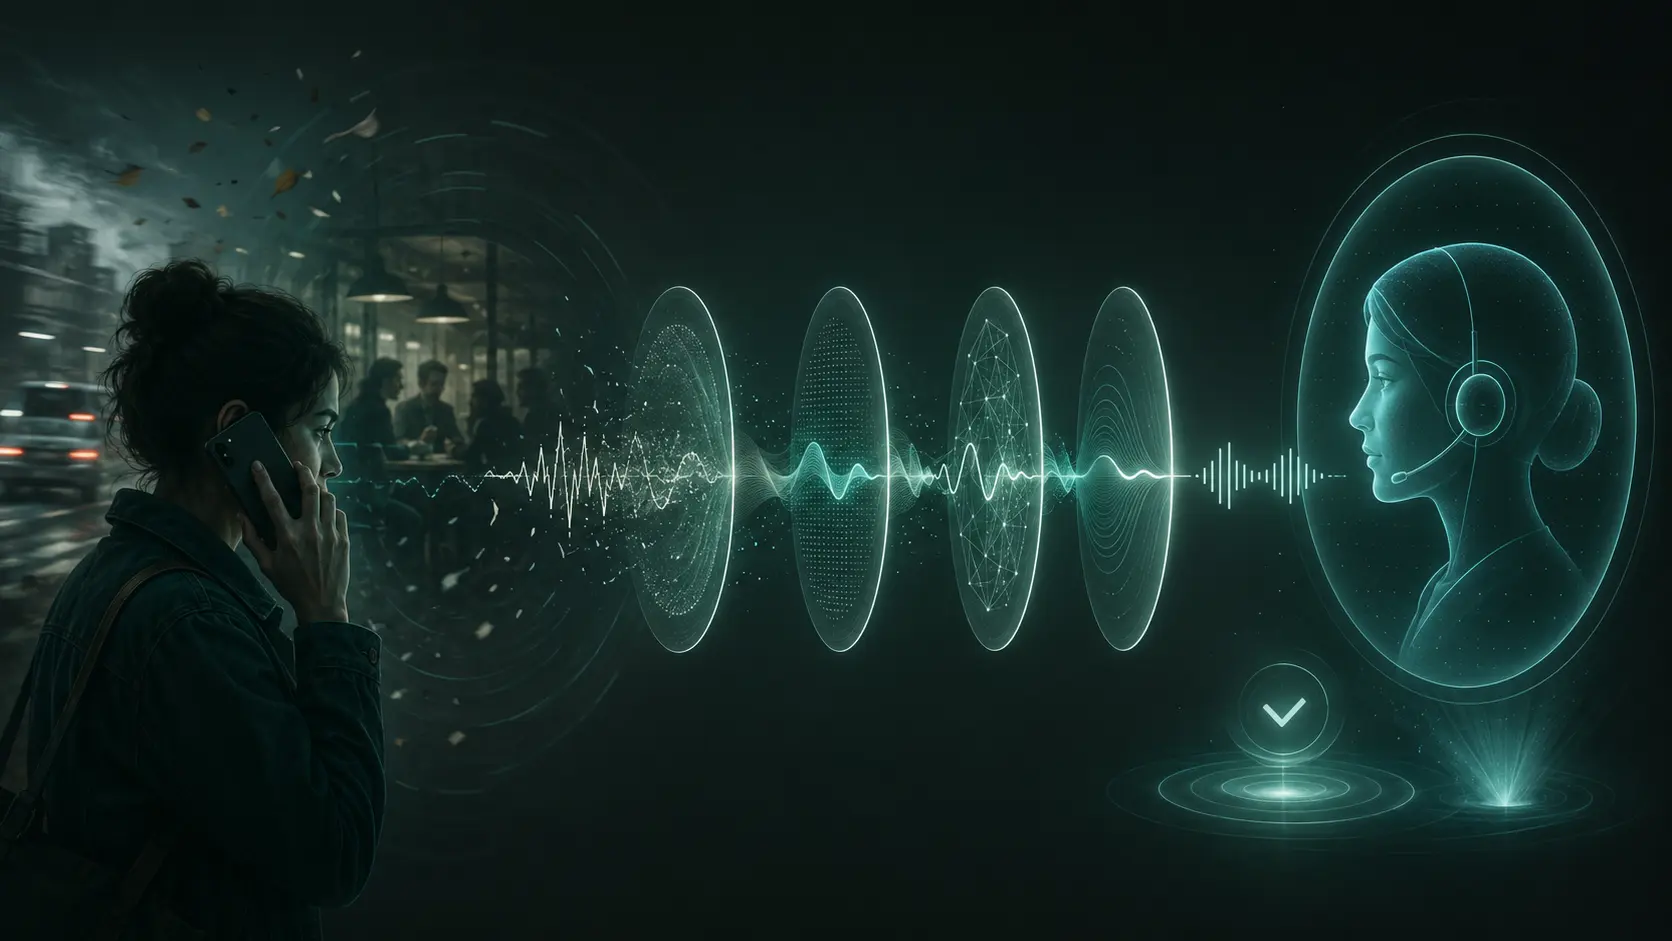
Graceful failure favors explicit uncertainty over a plausible but incorrect action.
ASR confidence should inform policy, but raw confidence is not a universal probability of correctness. Combine it with transcript stability, semantic plausibility, expected field format, acoustic quality, and the consequence of being wrong. Context can help repair minor errors. If the agent asks for a city and gets a close phonetic match to a known service area, it can confirm the candidate. Context should constrain interpretation, not silently overwrite what the caller said.
Use an escalating recovery ladder:
Confirm a likely value: "I heard 51 King Street. Is that correct?"
Request a specific field again: Ask only for the unclear surname, date, or reference number.
Change delivery: Suggest slower speech, moving away from noise, or using the handset instead of speakerphone.
Offer another channel: Send a secure text or defer data entry when the workflow supports it.
Escalate to a human: Transfer when repeated uncertainty, severe clipping, persistent overlap, or network loss prevents reliable automation.
For consequential actions (payments, cancellations, identity verification) clarification beats confidently proceeding on a wrong interpretation. Reprompt wording should name the problem without blaming the caller: "The connection cut out while you said the account number. Please repeat the last four digits." Getting this right often protects AI phone call accuracy more than forcing every turn through the workflow unchanged.
How should teams test poor audio before deployment?
Build a realistic scenario matrix
Clean studio speech establishes a baseline, not production readiness. Capture or simulate streets, vehicles, cafes, offices, speakerphone echo, quiet talkers, clipping, hold music, and competing conversations. Pass samples through the codecs and routes used in production. Inject weak mobile conditions with packet loss, jitter, and dropouts. Cover accents, speaking rates, languages, devices, and both short commands and extended explanations.
Measure the pipeline and the outcome
Metric | What it reveals |
|---|---|
Word Error Rate (WER) | Recognition errors by environment, codec, speaker group, and noise condition |
End-to-end latency | Delay from speech arrival to transcript, decision, and audible response |
Interruption accuracy | Valid barge-ins accepted versus missed or accidental interruptions |
False speech triggers | Noise events incorrectly treated as caller turns |
Whether callers finish the business workflow correctly | |
Recovery and transfer rate | How often clarification succeeds or audio forces escalation |
Review both objective metrics and human judgments. ITU-T P.835 provides a methodology for rating speech signal quality, background noise, and overall quality independently. Pair listening tests with WER and task results, because clean-sounding enhancement can still damage ASR. Re-run the suite whenever you change media providers, codecs, denoisers, VAD settings, ASR models, prompts, or interruption policy.
Production checklist: Verify codec negotiation and sample rates; monitor clipping, level, jitter, and packet loss; tune denoising and VAD together; test quiet speech and overlapping talkers; validate echo cancellation during playback; inspect partial and final transcripts; define confidence policies; test targeted reprompts; confirm human transfer behavior; and set release thresholds for latency, false triggers, WER, interruption accuracy, and task completion.
Practical takeaways
Production robustness comes from treating audio as a system. Trace failures from the caller's environment through the microphone, network, codec, media service, VAD, ASR, turn detector, and dialogue policy. Combine conservative enhancement with models trained for degraded telephony, then tune the entire path against representative calls.
Before launch:
Optimize for intelligibility and task success, not maximum noise removal.
Treat low confidence as a dialogue event that requires confirmation, repetition, or escalation.
Measure WER, latency, false triggers, interruption accuracy, and task completion by scenario.
Include streets, vehicles, offices, cafes, low-volume callers, weak connections, overlap, and barge-in in every regression suite.
Revisit the broader architecture through this complete guide on AI phone agents when changing telephony or conversational components.
The practical standard for AI phone agents handling background noise is not perfect transcription under every condition. It is knowing when evidence is unreliable, recovering without inventing intent, and handing the conversation to a person when the channel can no longer support safe automation.
Frequently asked questions
Can noise suppression fix every bad call?
Why does background conversation confuse the system more than a fan?
Should the agent raise microphone gain for a quiet caller?
How should the system handle two people speaking at once?
When should a call transfer to a human?