Benchmarks
Voice AI Benchmarks: Speech-to-Text, Text-to-Speech & Speech-to-Speech
Real-world and public-benchmark results for Pulse, Lightning and Hydra, with full methodology and reproducible scripts.
Last updated
19 Aug 2026
Section 01
Three numbers, three levels of proof
Every figure on this page carries a badge naming who measured it. Only one of these three is independently verifiable, and we say so.
Pulse Pro · STT
5.42%
Average ESB word error rate
Tied 2nd of 86 systems on the public Open ASR Leaderboard, across 8 datasets.
Lightning v3.1 · TTS
~200ms
Time to first byte
At 40 concurrent requests over WebSocket streaming. Real-time factor 3.3× on one L40S.
Providers compared on this page

Deepgram
Cartesia
OpenAI

AssemblyAI
Murf

Speechmatics

WellSaid

Soniox

Gladia

NVIDIA
ElevenLabs
Sarvam
Section 02
Latency comparison
Plotted on a shared millisecond scale so the real spread is visible. Averages hide the calls that feel broken, so percentiles appear wherever they exist.
Speech-to-text, time to first transcript
Sorted fastest first. Solid marker is a point measurement, capsule is a P50 to P90 span.

Speechmatics Flow publishes only a sub-1 second figure, too coarse to plot honestly.
Under 150 ms
150 to 300 ms
Over 300 ms
Smallest measured
Speko
Text-to-speech, time to first audio
Sorted fastest first. Vendor ranges are drawn as capsules across their whole span, not collapsed to a midpoint.

Murf and Cartesia are faster than Lightning on these figures. Cartesia's is a 90th percentile and WellSaid's is per 30 characters, so the set is not measured like for like.
Under 200 ms
200 to 300 ms
Over 400 ms
Smallest measured
Our own numbers disagree. Internal sources give Pulse time to first transcript as both 64 ms and 70 ms, and Deepgram Nova 3 as both 71 ms and 100 ms. Lightning appears as 100 ms end-to-end on our comparison pages and ~200 ms time to first byte in the docs, and end-to-end cannot be faster than its own first byte. The conservative figure is plotted for us and the favourable one for competitors until a single run settles it.
Why percentiles, not means
A voice agent is judged on its worst turns. A model with a 200 ms mean and a 2 second P99 feels broken more often than one with a 300 ms mean and a 400 ms P99, and a mean cannot tell you which one you have. We publish percentiles where we have them and mark the gap where we do not.
Speech-to-text, time to first transcript
Section 03
How we benchmark
The parameters stated up front rather than hidden behind a disclosure. Public benchmarks can be overfitted and gamed, which is an argument for showing your method, not for hiding behind one number.
Datasets
ESB suite, 9 datasets, English. FLEURS for multilingual, 26 languages. WildASR for degraded recording conditions. Internal English and Hindi perturbation suites. EmergentTTS, 1,088 samples drawn from the 1,645-sample public set. AIEWF, 300 tasks over 10 runs of 30 turns. Plus 44 real Hindi-English collections calls.
Accuracy metric
Word error rate under the Whisper normalizer, with character error rate alongside. This choice is material: a third-party board reported Pulse at 8.0% where inverse text normalisation scored spelled-out numbers as errors, against 5.1% otherwise. On numbers-heavy call audio the normaliser changes the answer.
Latency metric
Time to first transcript runs from end of speech to complete transcript. Time to first byte is the first audio byte received. Voice-to-voice is end of user speech to start of agent audio. Reported as P50, P90, P95 and P99 wherever the run produced them.
Ground truth
Manual human transcription for the call benchmark. Public datasets use their own published references, unmodified.
Hardware
Throughput on a single L40S, 48 GB. Streaming tests at 16 kHz linear16. Competitor models called through their public production APIs, not self-hosted.
Refresh cadence
Quarterly, and immediately when any model in the comparison set ships a new version. Every table carries its own measurement date.
Reproduce it
The evaluation walkthrough and scripts are public, and every result below can be regenerated against your own audio.
Section 04
Speech-to-text
Switch regimes to see the same models on clean benchmark audio and on real call recordings.
Clean benchmarks
Real call audio
ESB suite word error rate by domain. Lower is better, green marks the best model in each row.
Domain
Audiobook, clean
Audiobook, noisy
Crowdsourced
Parliament
TED talks
Podcasts
Financial
Earnings calls
Meetings
Overall
Dataset
LibriSpeech Clean
LibriSpeech Other
Common Voice
VoxPopuli
TED-LIUM
GigaSpeech
SPGISpeech
Earnings22
AMI
Aggregate
Pulse
2.46
5.31
10.89
7.16
4.07
10.43
2.86
12.25
10.58
7.33
AssemblyAI
1.65
2.86
6.73
7.28
2.95
9.12
1.74
11.52
14.60
6.49
Deepgram
3.20
6.60
14.22
9.55
3.59
10.05
2.99
15.79
17.04
9.23
ElevenLabs
1.97
4.45
9.83
7.91
3.16
9.66
4.40
12.20
12.23
7.31
Smallest's Pulse achievement. Pulse wins parliamentary speech and meetings, the two hardest multi-speaker conditions. Note also that Pulse streams at 7.33 aggregate here, while the 5.42% headline is Pulse Pro on the pre-recorded path. They are different models. While Assembly AI leads 7 of 9 domains and the aggregate, and ElevenLabs Scribe edges Pulse overall by 0.02.
FLEURS streaming word error rate by language, Pulse against Deepgram Nova 3
LANGUAGE
Italian
Spanish
English
Portuguese
Hindi
Germen
French
Marathi
Gujarati
PULSE
4.41
5.99
6.03
8.32
8.30
9.50
10.71
15.68
20.05
Deepgram NOVA 3
6.99
7.55
11.21
11.46
15.46
10.15
12.07
not supported
not supported
RATIO
1.6x
1.3x
1.9x
1.4x
1.19
1.1x
1.1x
Marathi and Gujarati have no Deepgram column because the model does not cover them. Coverage is itself a result.
Smallest measured
WildASR robustness, word error rate under degraded recording conditions
CONDITION
Clean Audio
Accented speech
Phone codec
Background noise
Reverberation
Far-field mic
Clipping
Overall
Pulse
5.98
5.82
7.19
8.90
9.06
13.38
14.03
9.63
AssemblyAI
3.33
2.80
3.45
4.04
23.50
26.07
6.59
12.52
Deepgram
11.62
7.31
9.13
15.04
27.27
62.99
43.35
28.17
ElevenLabs
4.24
4.01
4.98
6.30
6.48
7.38
11.20
6.74
ElevenLabs Scribe is the most robust model here overall. The useful finding is about failure modes: AssemblyAI is the most accurate on clean audio yet degrades to 26.07 far-field and 23.50 on reverberation, and Deepgram reaches 62.99 far-field. Pulse loses most single conditions but never collapses on any of them, which is what matters when you cannot control how your callers are recorded.
Smallest measured
Pulse: 21 streaming languages, 26 pre-recorded.
Pulse Pro: English only, HTTP only, streaming worker on roadmap. Throughput 250-300x real time on 1x L40S.
Pricing: our own materials quote $0.003, $0.004, $0.005 and $0.008 per minute for real-time Pulse. Not published here until reconciled.
Section 05
Public benchmarks vs your actual audio
Our Hindi word error rate is 8.30% on FLEURS and 29.1% on real collections calls. Both are measured. Neither is wrong.
Same model, same language, two kinds of audio
Word error rate. Lower is better.

Read-speech benchmarks measure clean, scripted audio recorded in good conditions. Production calls are code-switched, noisy, spontaneous and compressed by telephony codecs. The gap is roughly 3.5× for us and 3.5× for Sarvam, so it is a property of the audio rather than of any one model.
We publish both because a single number would mislead you. Whichever figure a vendor quotes, it is probably the easier one, and the only number that predicts your production accuracy is the one you measure on your own recordings.
Section 06
Real Hindi-English call audio
Five providers on 44 real collections calls, scored against manual human transcripts. We win two of six categories. The other four are published unchanged.
Green marks the category winner. Recall scores run 0 to 1, higher is better. July 2026.
Dataset
SMALLEST AI
PULSE
DEEPGRAM
NOVA 3
SERVAM AI
Saaras
ELEVENLABS
Scribe, KEYTERMS
ELEVENLABS
Scribe, standard
WER
0.291
0.325
0.376
0.460
0.554
LOAN TERMS
0.872
0.919
0.910
0.902
0.815
PROMISE TO PAY
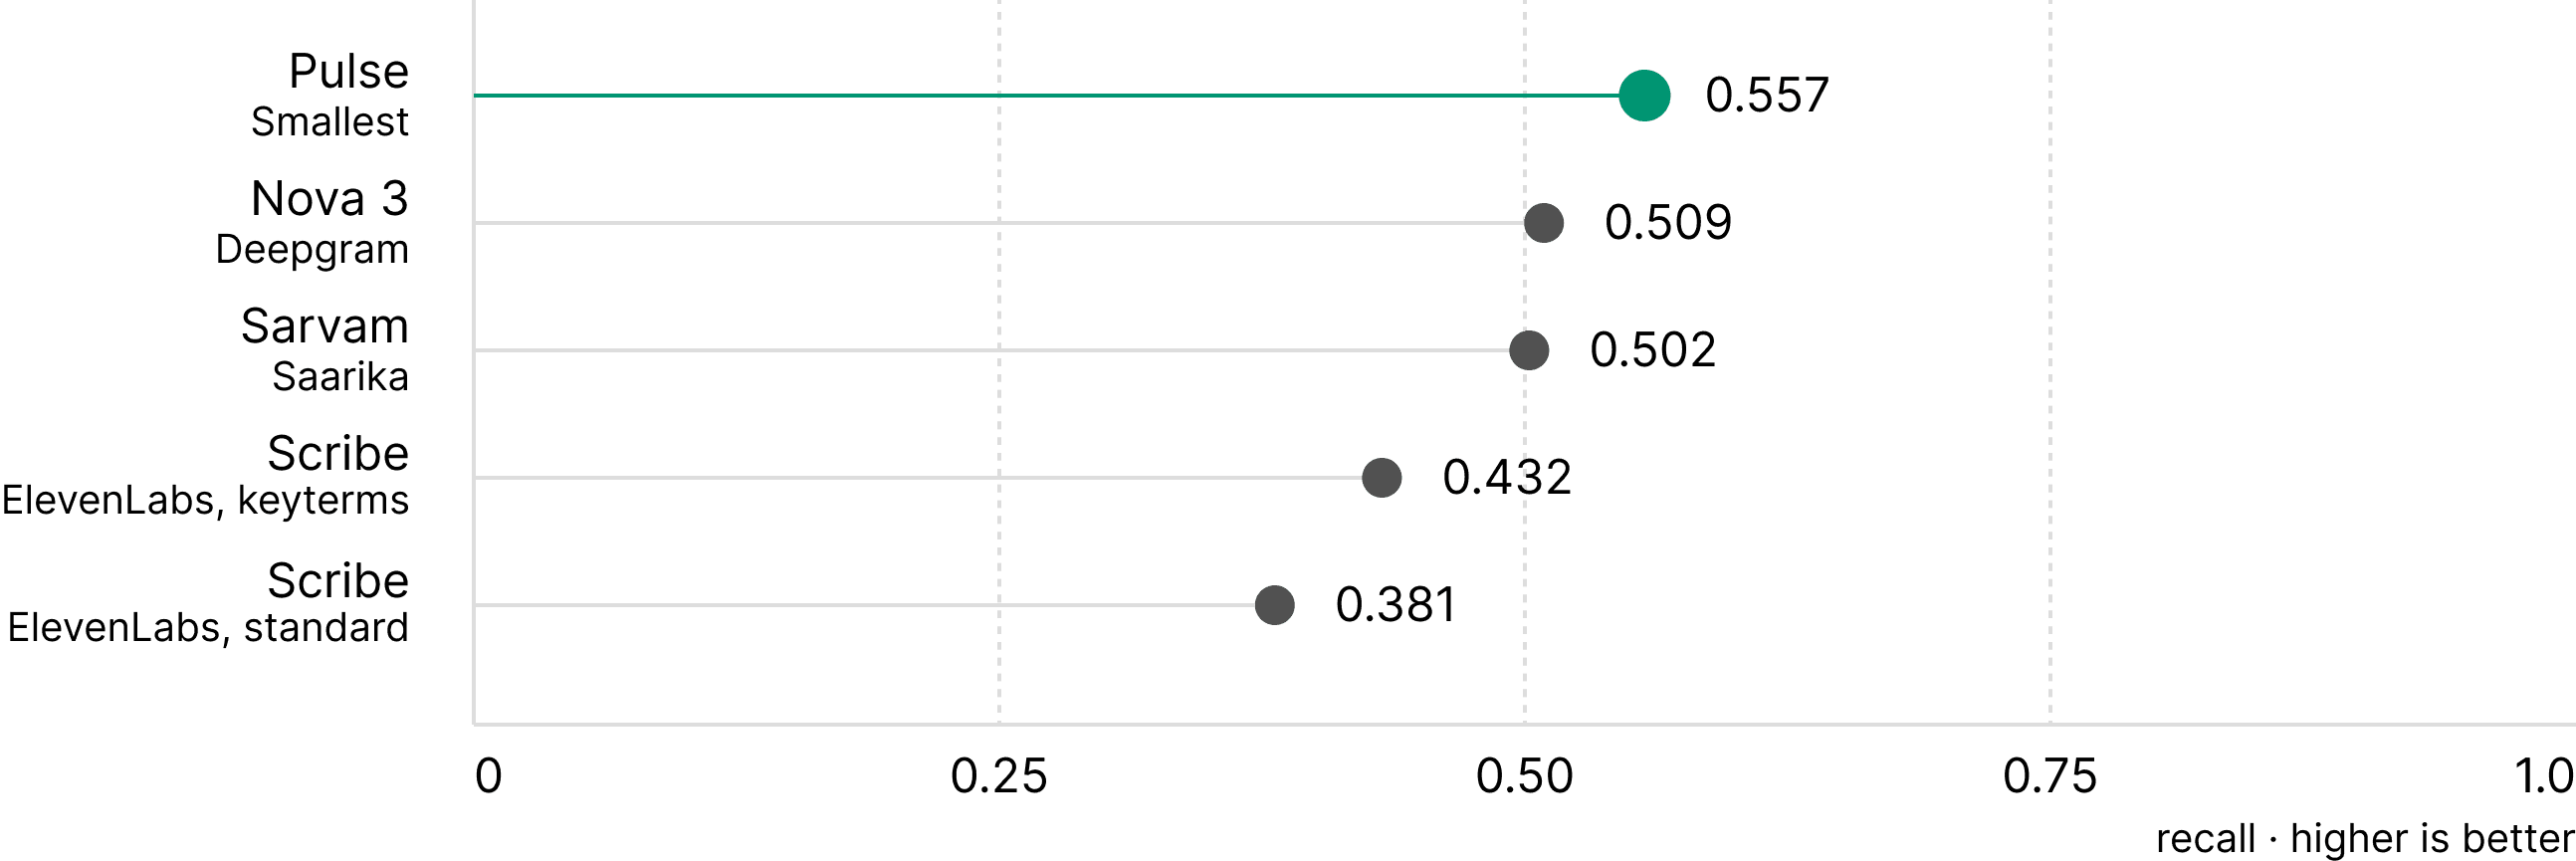
0.557
0.509
0.502
0.432
0.381
NUMBERS
0.387
0.282
0.381
0.410
0.389
AMOUNT
0.334
0.280
0.330
0.349
0.313
DATES
0.531
0.510
0.522
0.611
0.485
What to take from this
Pulse gives the most accurate and most consistent transcript. Deepgram is strongest on loan terminology. ElevenLabs Keyterms captures financial entities best but produces a noticeably worse transcript around them. Always choose Keyterms over standard ElevenLabs; it wins every metric at the same speed and cost.
An industry-wide gap
Across all five providers, amounts and numbers recall stayed low and none cleared 0.35. That is an unsolved problem for the whole category rather than a gap in any one product, and it means any amount-critical workflow needs a verification step whichever API you choose.
Scope and limits. 44 recordings, July 2026, Hindi-English collections and loan-servicing calls from a single domain. Ground truth is manual human transcription. The dataset carries no noise-condition labels and no language-mix breakdown, so nothing here supports a conclusion about specific noise levels or code-switching ratios. At n=44, small gaps between adjacent models may not be significant.
Source data and further reading
Section 07
Entity-level recall
Word error rate treats every word as equal. In a collections call, one missed rupee figure matters more than ten missed filler words. No public leaderboard measures this, so we defined it.
Loan terms
Did the model capture loan vocabulary such as EMI, tenure and interest.
Promise to pay
Did it capture commitment phrases such as "I will pay by" or "will transfer today".
Numbers
Did it correctly transcribe spoken numeric values.
Amounts
Did it capture spoken rupee figures.
Scoring
All scored 0 to 1 and averaged over 44 recordings. These are Smallest-defined metrics. The term lists and matching logic still need publishing before an outside team can reproduce them.
Promise-to-pay recall
Higher is better, on the full 0 to 1 scale so the true size of the gaps is visible.
Amounts recall
The dashed line marks 0.35. No provider clears it.

Section 08
Text-to-speech
Blind head-to-head listener preference on the EmergentTTS benchmark, then the same models rated dimension by dimension.
Lightning win rate against each competitor
1,088 samples. The solid line is 50%, where neither model is preferred.
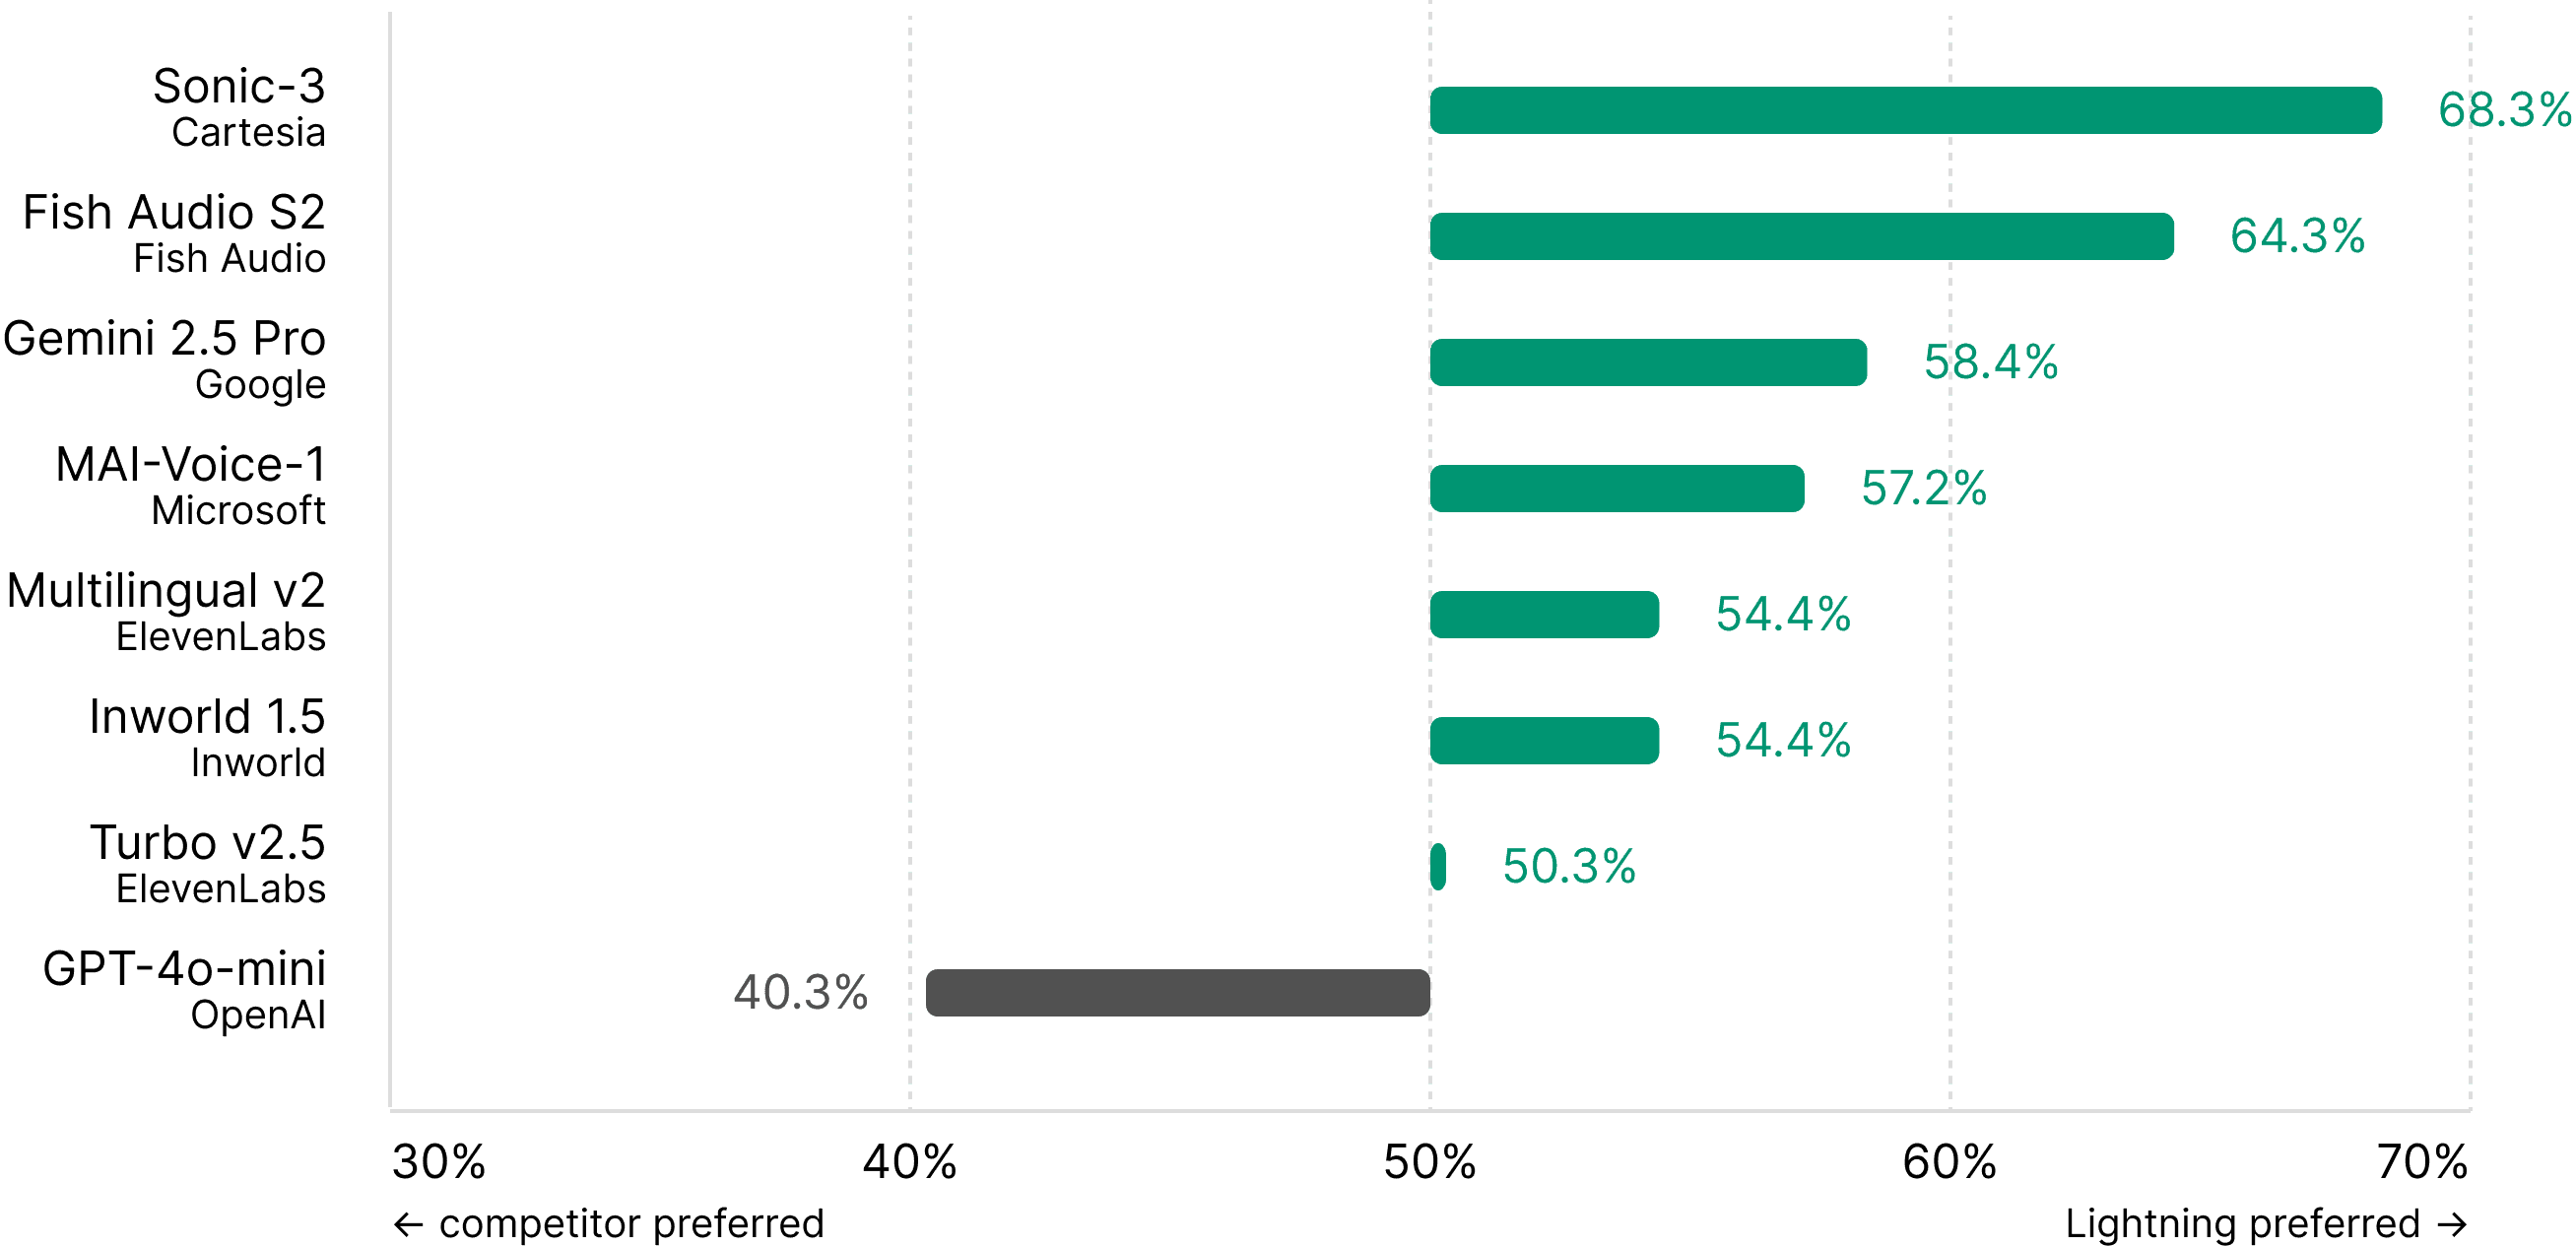
GPT-4o-mini TTS beats Lightning on this benchmark. That row stays in. The 1,088 samples are a subset of the 1,645-sample public EmergentTTS set.
Smallest measured
Naturalness
Metric
Overall
Naturalness
Intonation
Prosody
Lightning Pro
3.16
2.55
3.06
2.81
GPT-4o-mini
3.13
2.41
3.06
2.73
EL Turbo v2.5
3.16
2.52
3.07
2.73
Sonic-3
3.20
2.57
3.12
2.83
EXPRESSIVENESS
Overall
Paralinguistics
Emotions
3.55
3.64
3.47
3.45
3.60
3.30
3.44
3.59
3.28
3.38
3.56
2.83
MOS V2
Mean MOS
UTMOS, predicted
WV-MOS, predicted
4.22
3.77
5.05
4.16
3.76
4.55
3.98
3.37
4.60
3.76
2.77
4.76
DELIVERY
Natural pace
Pause placement
Breathing naturalness
Pronunciation style
Boundary consistency
4.72
4.66
3.82
4.98
4.96
4.57
4.54
3.06
4.96
4.94
4.51
4.49
3.14
4.95
4.93
4.01
4.28
2.79
4.96
4.93
Performance Lightning's advantage is expressiveness, delivery and breathing, where the gap is large: 3.82 against 2.79 on breathing naturalness. This also contradicts the head-to-head chart above, where Lightning was preferred over Sonic-3 68.3% of the time. Blind preference and dimensional rating measure different things, and both are reported rather than only the flattering one. UTMOS and WV-MOS are model-predicted, not human ratings.
Synthesis accuracy, transcribed back with Whisper and scored against the input text
Metric
Lightning v3.1
Lightning v3.1 Pro
wer
1.57%
1.36%
cer
0.67%
0.40%
hallucination
0.03%
0.00%
15 languages including Hindi, Tamil, Kannada, Telugu, Malayalam, Marathi and Gujarati, with automatic language detection and mid-sentence switching.
Time to first byte ~200 ms at 40 concurrent streams.
Pricing: three different figures appear across our own materials for the same product, $0.05, $0.145 and $0.175 per 10K characters. Not published here until reconciled.
Source data and further reading
Section 09: Beta
Speech-to-speech
Voice-to-voice latency across 9 production models on the AIEWF benchmark: 300 tasks, 10 runs of 30 turns
Tool-call voice-to-voice latency, mean
Lower is better. The dashed line marks 2 seconds, where a turn starts to feel slow.

Non-tool voice-to-voice median is 864 ms, tied fastest of the set. Percentile distributions are not yet published.
Smallest measured
Task performance, AIEWF pass rate and Audio MultiChallenge
MODEL
Hydra
Ultravox v0.7
GPT Realtime 1.5
GPT Realtime
GPT Realtime 2
WER
95.9
97.7%
93.3%
86.7%
not run
Audio multichallenge
35.52%
not run
34.73%
not run
37.61%
Source data and further reading
Section 10
Methodology and changelog
Dataset inventory, provenance policy, and the open items we have not resolved.
Dataset inventory
BENCHMARK
ESB suite
FLURS
WildASR
EmergentTTS
AIEWF
Audio MultiChallenge
Hindi-English calls
Perturbation suites
Scope
9 datasets, English
26 languages, read speech
7 degradation conditions
1,088 of 1645 samples
300 tasks, 10x30 turns
Multi-turn audio reasoning
44 collections recordings
English and Hindi
used in
Section 04
Section 04, 05
Section 04
Section 08
Section 09
Section 09
Section 05, 06, 08
Section 04
publicly available
Yes
Yes
Yes
Yes
Yes
Yes
No, Internal
No, Internal
Section 11
FAQ
Why do your two Hindi numbers differ so much?
What is word error rate?
What is the difference between TTFB, TTFT and voice-to-voice?
Are these numbers independent?
Which model should I use for noisy call audio?
Do you support Hindi and code-switching?